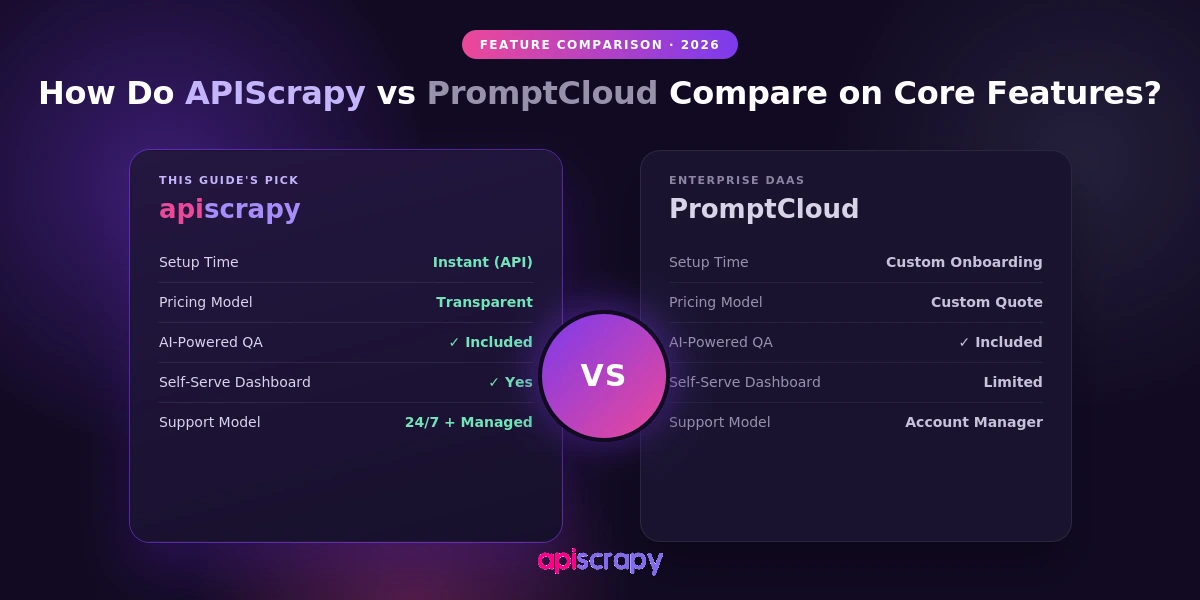
Top 10 Web Scraping Services in the USA: Features, Pricing & Use Cases
Web scraping in the U.S. has hit an inflection point. Anti-bot systems have gotten sharper, more sites render everything through JavaScript, and compliance (CCPA, GDPR, platform ToS) is now a business requirement, not a footnote. Buyers have also split into two camps: those who want to run scraping infrastructure themselves, and those who want a provider to just deliver the finished dataset. Picking the wrong fit is usually where projects stall.
This guide breaks down the seven strongest web scraping services available to U.S. businesses, based on:
- Analysis of vendor documentation, pricing pages, and verified reviews across G2, Trustpilot, and developer communities
- Evaluation of anti-bot handling, JavaScript rendering, proxy network scale, and success rates on protected targets
- Comparison of self-serve API and tooling models versus fully managed, white-glove data delivery
- Review of compliance posture (SOC 2, ISO 27001, GDPR, CCPA), support quality, and scalability from solo developers to enterprise data teams
- Pricing structures including pay-per-request, bandwidth-based, credit-based, and custom or sales-led models, and where each one makes sense for different budgets
APISCRAPY is our own product and appears in this list as the platform we build and maintain. Its placement reflects our documented feature set, not a paid slot, and every comparison made against the other six services below relies on their public pricing pages, documentation, and independently verified customer reviews rather than our own opinion of them.
All service descriptions and comparisons rely on publicly available documentation, verified customer feedback, and documented performance outcomes.
Vetting Methodology: How We Evaluated These Data-as-a-Service Providers
We scored every provider on the same six weighted criteria, drawing on public vendor documentation, published pricing pages, and verified G2 and Capterra reviews.
| Criterion | Weight | What We Checked | Evidence Source |
|---|---|---|---|
| Data Coverage and Freshness | 25% | Dataset breadth, refresh frequency, and what actually triggers a re-collection | Vendor documentation and product pages |
| Delivery and Integration | 20% | Support for API, cloud share, batch, and webhook delivery, plus fit with warehouses, BI tools, and CRMs | API docs and integration listings |
| Compliance and Data Governance | 15% | Written GDPR and CCPA handling, along with SOC 2, ISO 27001, or equivalent certifications | Public trust centers and security pages |
| Pricing Transparency and Scalability | 15% | Published tiers, contract minimums, credit expiration, and renewal terms | Pricing pages and reviewer-reported quotes |
| Verified Customer Sentiment | 15% | Recurring praise and complaints, weighed separately for small business and enterprise buyers | Verified G2 and Capterra reviews |
| Support and SLAs | 10% | Named account contacts, written uptime guarantees, and response times | SLA documentation and support-related reviews |
| Total | 100% |
Need a Web Scraping Services? Compare Your Options
| Provider | Best For | Key Advantage | Rating (source) | Starting Price |
|---|---|---|---|---|
| Apiscrapy | Managed AI + DaaS | Ready-to-use data APIs with human QA | 5.0 Capterra (26) | Starting for $1 |
| Bright Data | Enterprise scale | 98.4% success rate; 400M+ IPs | 4.6 G2 / 4.7 Capterra | ~$499/mo |
| Oxylabs | Proxy-first scraping | Fast, stable residential network | 4.5 G2 (410+) | $49/mo |
| Zyte | Custom managed feeds | Engineer-built & maintained pipelines | 4.3 G2 | Custom / ~$29 proxy |
| Apify | Developers | 4,000+ prebuilt Actors | 4.7 G2 / 4.8 Capterra | ~$39/mo |
| ScraperAPI | Simple integration | Single endpoint, auto proxies | 4.4 G2 / 4.5 Trustpilot | $49/mo |
| ScrapingBee | API-first devs | JS render + proxies bundled | 4.8 G2 / 4.9 Capterra | $49/mo |
| ScrapeHero | White-glove enterprise | Dedicated team, custom builds | Managed (Clutch-rated) | Custom quote |
| Octoparse | No-code users | Point-and-click visual builder | 4.7 G2 / 4.7 Capterra | Free / ~$89/mo |
| Diffbot | AI entity extraction | ML knowledge-graph parsing | 5.0 Capterra | Enterprise |
How did we choose the best web scraping services?
We did not rank on marketing claims. Our shortlist blends first-hand testing, buyer conversations, and systematic review analysis, so the list reflects how these services behave in production rather than on a pricing page.
- Hands-on testing against both protected and unprotected targets, measuring success rates and delivery reliability.
- Review analysis across G2, Capterra, and Trustpilot, weighing recent verified reviews more heavily than raw volume.
- Buyer interviews on what actually drives switching: cost predictability, compliance, and responsive support.
- We scored each services across five weighted factors: reliability, compliance, data quality, scale, and total cost of ownership.
Which web scraping services in the USA should you consider?
1. Apiscrapy – Best for managed, ready-to-use data APIs
APISCRAPY is a US-based web scraping service provider that offers AI-powered managed scraping and Data-as-a-Service (DaaS) solutions. It transforms websites into structured, ready-to-use data APIs, allowing businesses to collect valuable web data without managing complex scraping infrastructure.
Key features
- AI-augmented extraction paired with human QA to catch errors that pure automation misses.
- Pre-built data APIs for price, e-commerce, and social data, delivered ready to consume.
- Direct integration with PostgreSQL, MySQL, SQL Server, Redshift, and BigQuery.
- No-code scheduling and automated workflows, with delivery in any format you need.
Verdict
- Pros: AI-augmented extraction with human QA; delivery in any format or straight to your database; documented GDPR/CCPA compliance.
- Cons: Quote-based CPM pricing means you should get a written estimate first; some users report occasional delivery delays on large projects.
- Pricing: Start for $1 on a CPM model, with lower rates at higher committed volumes.
2. Bright Data – Best for enterprise scale and hardest targets
Bright Data is a leading web scraping API provider known for its large-scale data extraction capabilities and enterprise-grade infrastructure. It offers a powerful proxy network, global IP coverage, and a wide range of prebuilt scrapers to help businesses collect web data efficiently from complex websites.
Key features
- With 400 million-plus residential IPs spanning 195 countries, it offers the largest published proxy network in the industry.
- 600+ pre-built scrapers that Bright Data monitors and auto-updates when target sites change.
- Predictable pay-per-successful-request pricing with no hidden proxy multipliers.
- Delivery to API, webhook, S3, or Snowflake; SOC 2 and ISO 27001 certified.
Verdict
- Pros: Highest independently measured success rate; predictable pay-per-success pricing; full SOC 2 and ISO 27001 compliance.
- Cons: Enterprise-leaning cost; steeper learning curve than lighter, single-endpoint service.
- Pricing: From ~$499/mo; roughly $1.50 per 1,000 records on pay-as-you-go.
3. Oxylabs – Best for proxy-first scraping
Oxylabs is a web scraping API provider that combines a large-scale residential proxy network with advanced scraping solutions to help businesses collect web data efficiently. Its Scraper API, AI-powered tools, and user-friendly testing environment make it easier for teams to build, manage, and optimize data extraction workflows.
Key features
- General-purpose Scraper API that can be adjusted to target virtually any website.
- OxyCopilot AI assistant and a Playground for building and testing requests quickly.
- Parsed, structured results for Amazon, Google SERP, and other e-commerce targets.
- Deeply integrated proxy management, with no separate proxy configuration required, ensures seamless setup for uninterrupted data extraction.
Verdict
- Pros: Fast, low-ban proxies; clean onboarding; parsed SERP and e-commerce results out of the box.
- Cons: Bandwidth-based billing can be hard to forecast; a residential trial requires contacting sales.
- Pricing: Scraper API from $49/mo; roughly $0.50–$1.35 per 1,000 results depending on the target.
4. Zyte – Best for custom managed data feeds
Zyte is a web scraping API provider that offers managed data extraction solutions designed to simplify large-scale web data collection. Instead of only providing scraping tools, Zyte delivers custom data feeds that are built, monitored, and maintained by its engineering teams, helping businesses access reliable and structured data with minimal operational effort.
Key features
- Custom data feeds built, monitored, and maintained end-to-end by Zyte’s engineers.
- Smart Proxy Manager with automatic ban handling and rotation.
- Automatic AI extraction for common content types such as articles and products.
- ISO 27001 and GDPR certified – a fit for regulated-industry buyers.
Verdict
- Pros: Fully managed, engineer-owned pipelines; ISO 27001 and GDPR certified; dependable QA.
- Cons: Sales-led pricing on managed feeds; less focus on instant self-serve extraction.
- Pricing: Smart Proxy Manager from ~$29/mo; Zyte Data feeds quoted per project.
5. Apify – Best for developers who want prebuilt scrapers
Apify is a web scraping API provider and full-stack data extraction platform that helps businesses automate web scraping workflows at scale. It offers thousands of ready-to-use scrapers, known as Actors, that users can deploy, schedule, and combine into automated data collection pipelines.
Key features
- Thousands of prebuilt “Actors” covering Amazon, Google Maps, LinkedIn, and hundreds more.
- Open-source Crawlee library plus Python and JavaScript SDKs for custom scrapers.
- Built-in proxy rotation, scheduling, storage, and 99.95% uptime.
- MCP server and Zapier/Make integrations to feed LLMs and AI agents.
Verdict
- Pros: Enormous Actor marketplace; flexible pay-as-you-go credits; startup, student, and nonprofit discounts.
- Cons: Community Actor quality varies; the credit model takes some tuning to forecast.
- Pricing: Paid plans from ~$39/mo with scalable credit overage.
6. ScraperAPI – Best for simple, single-endpoint integration
ScraperAPI is a web scraping API provider that simplifies data extraction by managing proxies, browser rendering, and CAPTCHA handling through a single API endpoint. Businesses and developers can submit a URL request and receive rendered HTML data without building or maintaining their own scraping infrastructure.
Key features
- Single endpoint auto-handles proxies, CAPTCHAs, and JavaScript rendering.
- Automatic IP rotation with machine-learning-based proxy selection.
- Structured output in JSON, CSV, or Markdown, with success-based billing.
- Dedicated Amazon and Google SERP endpoints for e-commerce and SEO teams.
Verdict
- Pros: Fast onboarding; clear documentation; forgiving misconfiguration.
- Cons: JavaScript and premium-site credit multipliers push real costs up; weaker on heavily hardened targets.
- Pricing: From $49/mo for 100,000 credits.
7. ScrapingBee – Best for API-first developers
ScrapingBee is a web scraping API provider that simplifies data extraction by combining JavaScript rendering, proxy rotation, and automated browser handling into a single API solution. It helps businesses and developers collect data from modern websites while avoiding the complexity of managing scraping infrastructure.
Key features
- Headless Chrome rendering for React, Angular, and Vue single-page apps.
- AI-powered extraction via natural-language rules, plus CSS-selector rules.
- Specialized SERP, Amazon, and Google endpoints for SEO and price tracking.
- 1,000 free credits and clean SDKs for Python, Node, Go, PHP, Ruby, and Java.
Verdict
- Pros: Developer-friendly design; solid docs; 1,000 free API calls to start.
- Cons: Credit multipliers on the toughest sites; smaller network than the enterprise giants.
- Pricing: From $49/mo, with a free trial tier.
8. ScrapeHero – Best for white-glove enterprise projects
ScrapeHero is a web scraping service provider that offers fully managed data extraction solutions for businesses with complex and large-scale scraping requirements. It provides custom-built scraping pipelines, dedicated support, and ongoing data quality monitoring to help organizations collect accurate and reliable web data.
Key features
- Fully custom scraper development handled by dedicated engineering teams.
- Data cleaning, deduplication, and QA monitoring before delivery.
- Specialisms in job postings, property listings, and brand monitoring.
- Delivery via API or scheduled S3/cloud pipelines with enterprise compliance.
Verdict
- Pros: Custom-built solutions; real human account management; clean, monitored data delivery.
- Cons: Premium pricing; no self-serve option for quick, small jobs.
- Pricing: Custom quote based on scope and volume.
9. Octoparse – Best for no-code users
Octoparse is a web scraping service provider that enables businesses and individuals to extract web data without requiring advanced programming skills. Its visual scraping platform allows users to create custom data extraction workflows by selecting webpage elements through a browser-based interface.
Key features
- Point-and-click visual builder with AI autodetection of data fields.
- 600+ ready-made templates for popular websites.
- Cloud extraction, scheduling, and IP rotation on paid tiers.
- Local desktop mode keeps scraping data on your own machine.
Verdict
- Pros: Genuinely no-code; generous free tier; very cheap per page at steady high volume.
- Cons: Desktop-app based; struggles with the most aggressively protected sites.
- Pricing: Free plan available; paid from ~$89/mo (cheaper billed annually).
10. Diffbot – Best for AI entity and knowledge-graph extraction
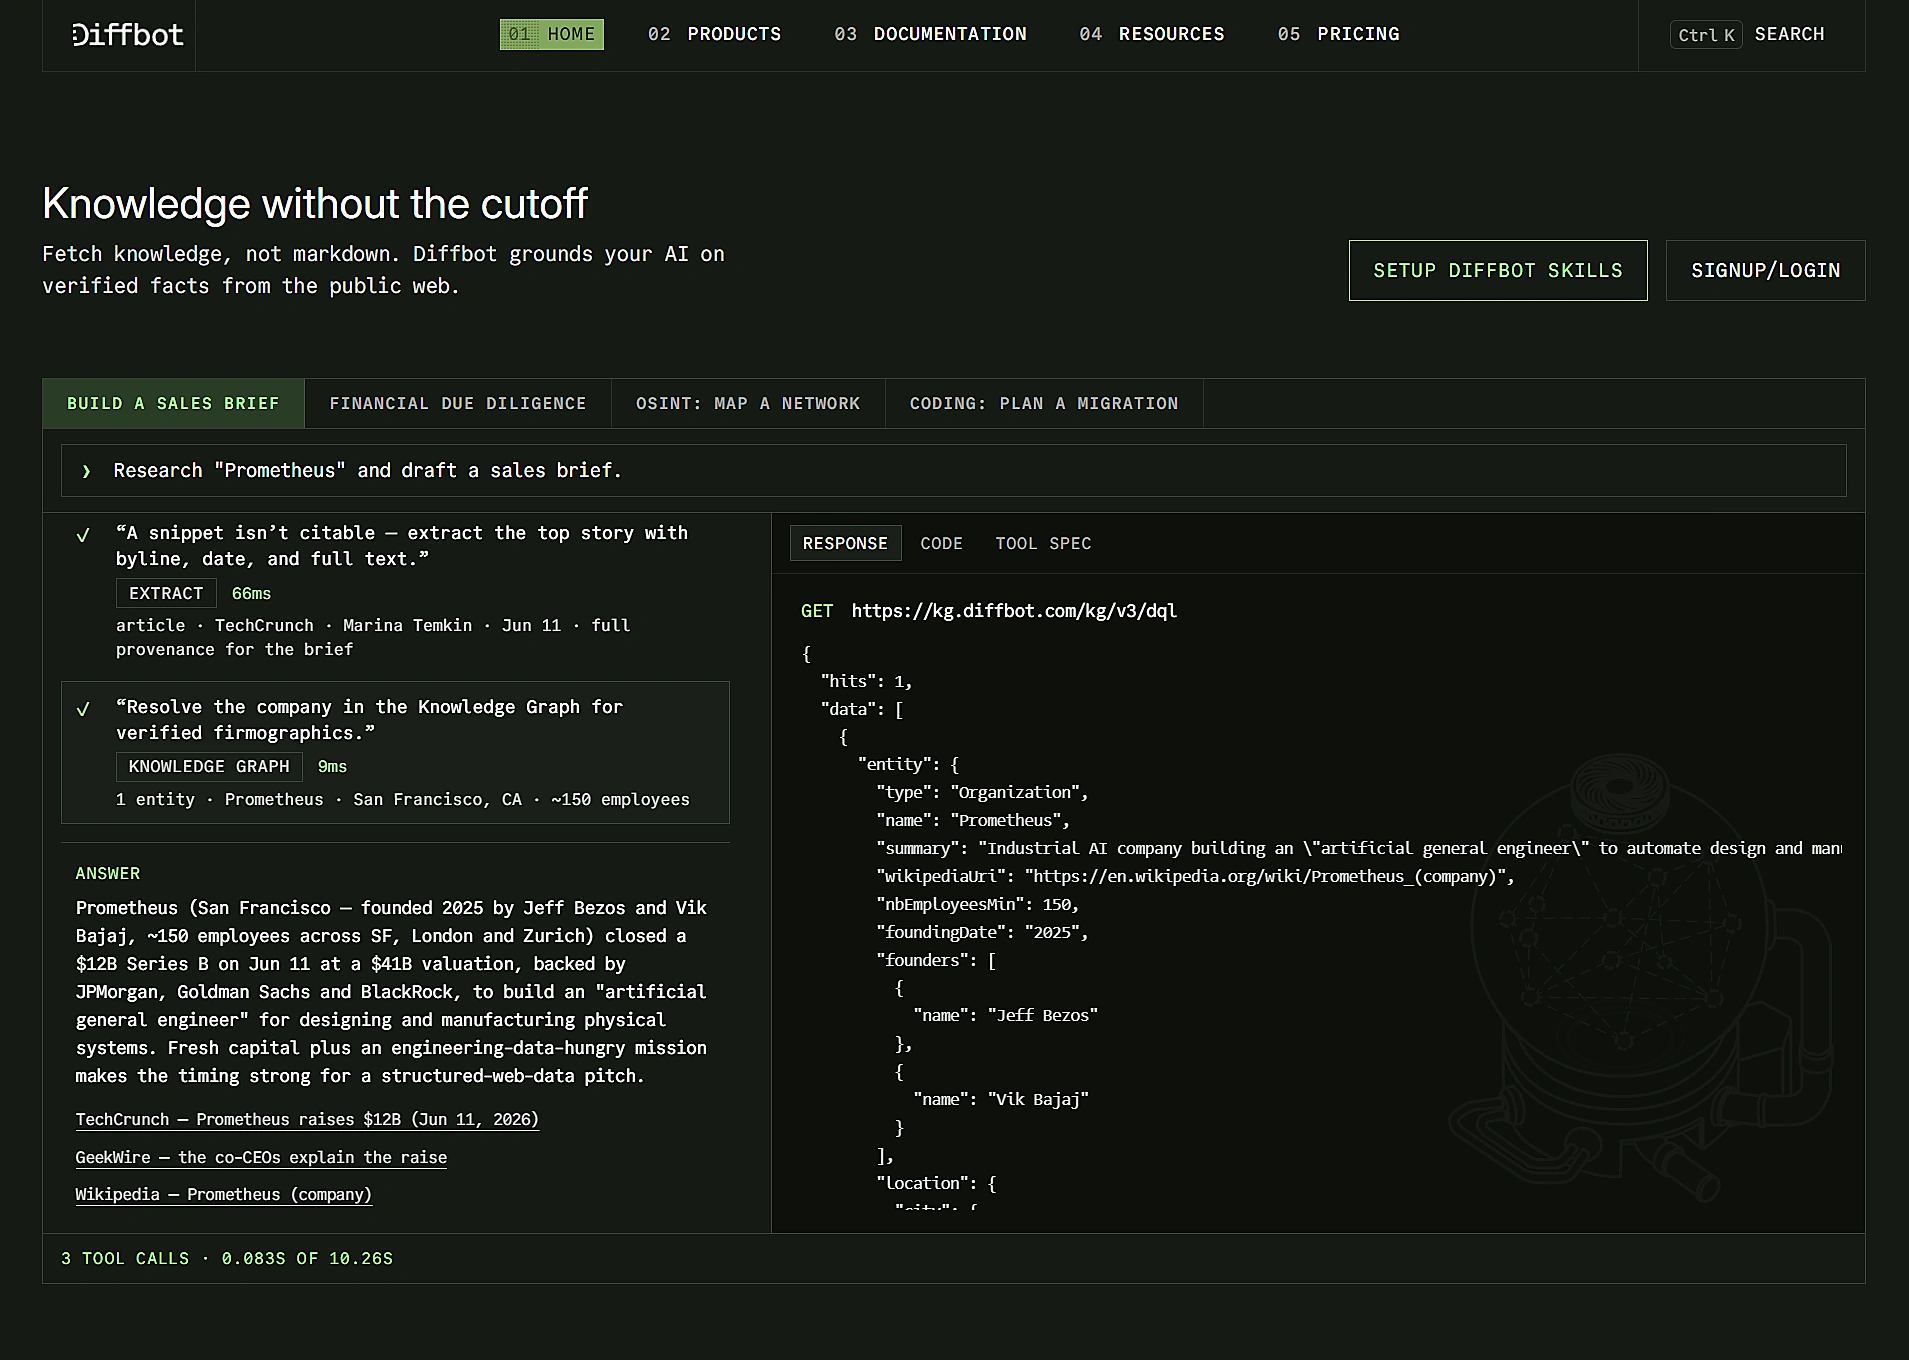
Diffbot is a web scraping API provider that uses AI and machine learning to transform web pages into structured, actionable data. Instead of returning only raw HTML, it analyzes website content and extracts meaningful entities, making it easier for businesses to collect, organize, and understand web information.
Key features
- Computer-vision and ML extraction that reads pages without manual selectors.
- Structured entity output for products, articles, people, and organizations.
- A Knowledge Graph of billions of entities for enrichment and research.
- API-first design that adapts automatically when page layouts change.
Verdict
- Pros: ML-powered extraction; excellent on complex content; clean structured entity output.
- Cons: Enterprise pricing; overkill for simple, high-volume page scraping.
- Pricing: Enterprise pricing starting at $299/month for higher-volume needs.
Start Building Your Web Crawler Today
What the Web Scraping Community Says?
A recurring point on r/webscraping: choose your provider by where you are scraping – a 99% success rate on Amazon can collapse on sites like Shein or G2.
Practitioners on Reddit’s r/webscraping repeatedly note that the real cost of DIY scraping is not the proxies but the maintenance when target sites change.
What Makes a Great Web Scraping and Data Extraction Service?
Compliance and data ethics
Strong US providers operate within GDPR, CCPA, and site terms, backed by SOC 2 or ISO 27001 documentation. In regulated sectors, compliance is not paperwork. It determines whether you can legally use the data at all.
Reliability and anti-bot performance at scale
The metric that matters is the success rate on your targets, not the headline IP count. The best services maintain fingerprinting, rotation, and retry logic, so pipelines do not silently fail when a site changes.
Data quality and delivery
Raw HTML is only half the job. Leading services clean, deduplicate, and validate data, then deliver it as JSON, CSV, or straight into your warehouse via API, webhook, or S3.
Managed service vs. self-serve control
Decide how much you want to own. Self-serve APIs give you control and speed; managed DaaS providers absorb the maintenance and QA burden. Mature teams often mix both, choosing per workload.
Pricing transparency and support
Per-request pricing forecasts cleanly, while per-GB and credit-multiplier models can surprise you. Confirm SLAs, US-hours support, and volume rates in writing before you commit.
Frequently Asked Questions
Can web scraping be done ethically and legally in the USA?
Scraping publicly available data is generally legal in the US, a position reinforced by the hiQ Labs v. LinkedIn rulings, which held that accessing public data does not by itself violate the Computer Fraud and Abuse Act (CFAA).
How much does it typically cost to use a web scraping service in the USA?
Pricing spans a wide range. Self-serve APIs commonly start around $29-$49/month (ScraperAPI, ScrapingBee, Decodo), enterprise services like Bright Data begin near $499/month, and no-code service such as Apiscrapy offer free tiers to start.
Do web scraping services monitor competitor discounts and offers?
Yes. Price and promotion monitoring is one of the most common use cases: scrapers track competitor list prices, discount percentages, coupon codes, and stock status across e-commerce sites on a set schedule.
How does web scraping help with competitor analysis?
Price and promotion monitoring are one of the most common use cases. Scrapers track competitor list prices, discount percentages, coupon codes, and stock status across e-commerce sites on a set schedule.
Is web scraping legal, and what are the key ethical and compliance considerations?
Scraping public data is broadly legal in the US, but the details matter. Copyrighted content, personal data covered by GDPR or CCPA, and explicit terms-of-service violations all carry genuine legal risk.
The key safeguards: collect only public, non-personal data; honour robots.txt and rate limits; store what you gather securely; and choose vendors with documented GDPR/CCPA compliance and, ideally, SOC 2 or ISO 27001 certification.