AI Data Extraction vs. Traditional Data Extraction: Which Is Best?

Businesses have relied on traditional data extraction for years to pull pricing, product, and market data from the web. As data volume grows and websites become more dynamic, more teams are asking whether AI data extraction delivers better accuracy with less upkeep.
This guide compares both approaches side by side so you can decide which one fits your data needs, technical resources, and budget.
The comparison below draws on:
- Hands-on testing of extraction workflows across static and dynamic websites
- Analysis of user reviews and forum discussions from data teams running both approaches
- Practitioner conversations with teams who maintain large-scale extraction pipelines
Disclosure: APISCRAPY, a managed AI data extraction service, appears in this article among the options discussed. That is noted here for transparency.
Whether you land on an AI-first approach, a traditional setup, or a mix of both, the goal of this guide is to help you find the right fit for your data operations.
What Is AI Data Extraction?
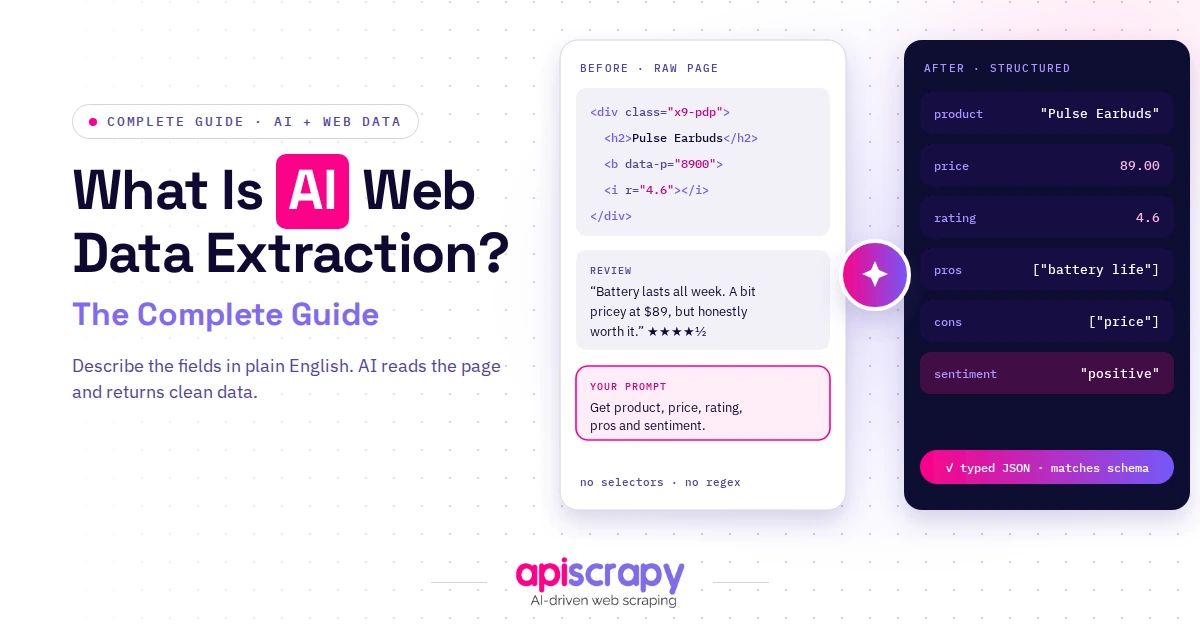
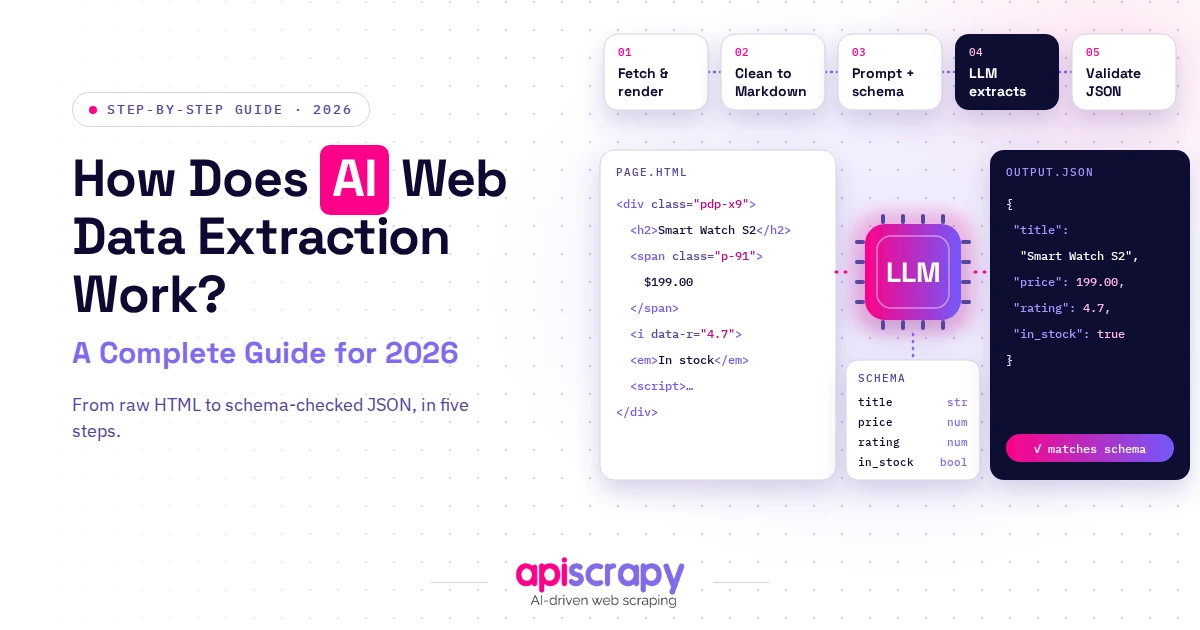
AI data extraction uses machine learning, natural language processing, and computer vision to identify and pull structured data from web pages without relying on fixed, position-based rules.
Data teams, product managers, and e-commerce businesses turn to it when source websites change layouts often or actively block conventional scraping methods.
In practice, it powers price monitoring, lead generation, real estate listing aggregation, and market research, adjusting automatically when a page’s structure shifts.
What Is Traditional Data Extraction?
Traditional data extraction relies on fixed rules such as CSS selectors, XPath expressions, or regular expressions written to match one page’s specific HTML structure.
Developers and technical teams use this approach when target websites have stable layouts and extraction needs are narrow and well defined.
It commonly powers scheduled scraping jobs, API-less data pipelines, and one-off data pulls where an in-house developer can maintain the script directly.
AI Data Extraction vs. Traditional Methods: How Do They Compare?
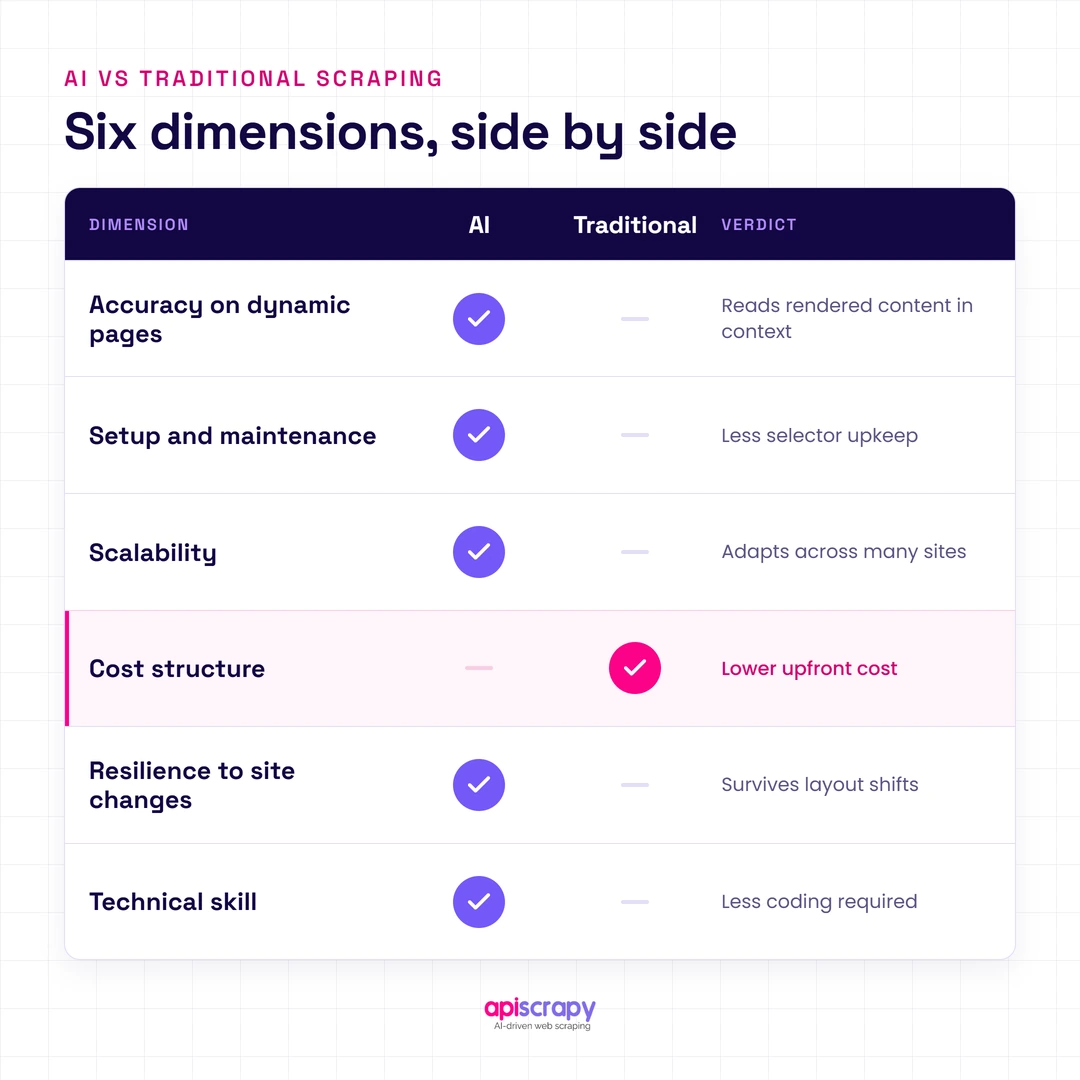
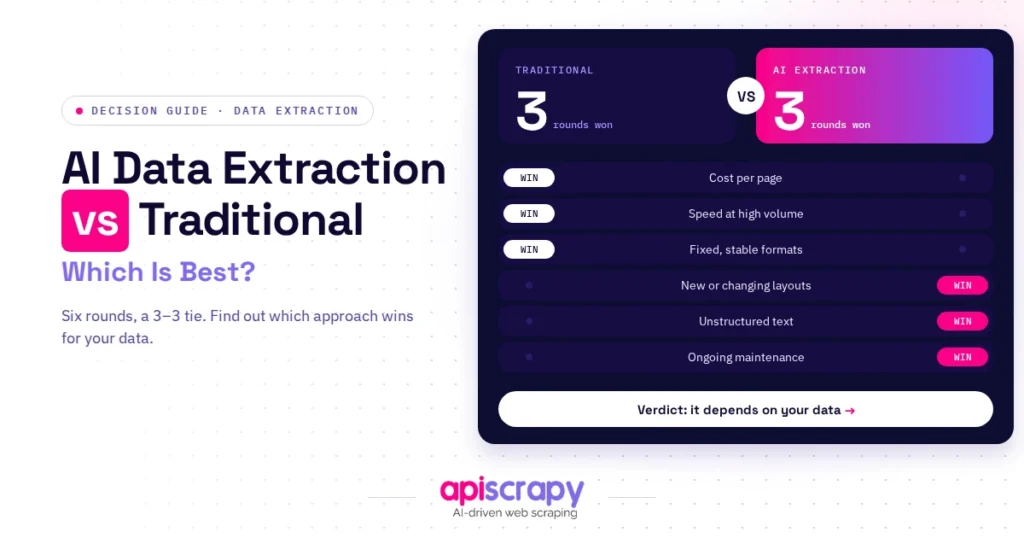
Both approaches solve the same problem in different ways, and the gap between them shows up clearly across six practical dimensions.
| Dimension | AI Data Extraction | Traditional Extraction |
|---|---|---|
| Accuracy on dynamic pages | Adapts to layout shifts using pattern recognition | Breaks when selectors no longer match |
| Setup and maintenance | Lower ongoing maintenance after initial setup | Requires frequent selector updates |
| Scalability | Scales across many sites with less manual tuning | Each new site needs a custom script |
| Cost structure | Usage-based pricing, often service-managed | Lower upfront cost, higher engineering time |
| Resilience to site changes | Detects structural changes automatically | Fails silently until manually fixed |
| Technical skill required | Minimal coding needed for business teams | Requires developer or scraping expertise |
Accuracy and Adaptability
AI-based extraction recognizes data by pattern rather than fixed page position, so it keeps working when a site redesigns its layout or adds new elements.
Cost and Scalability
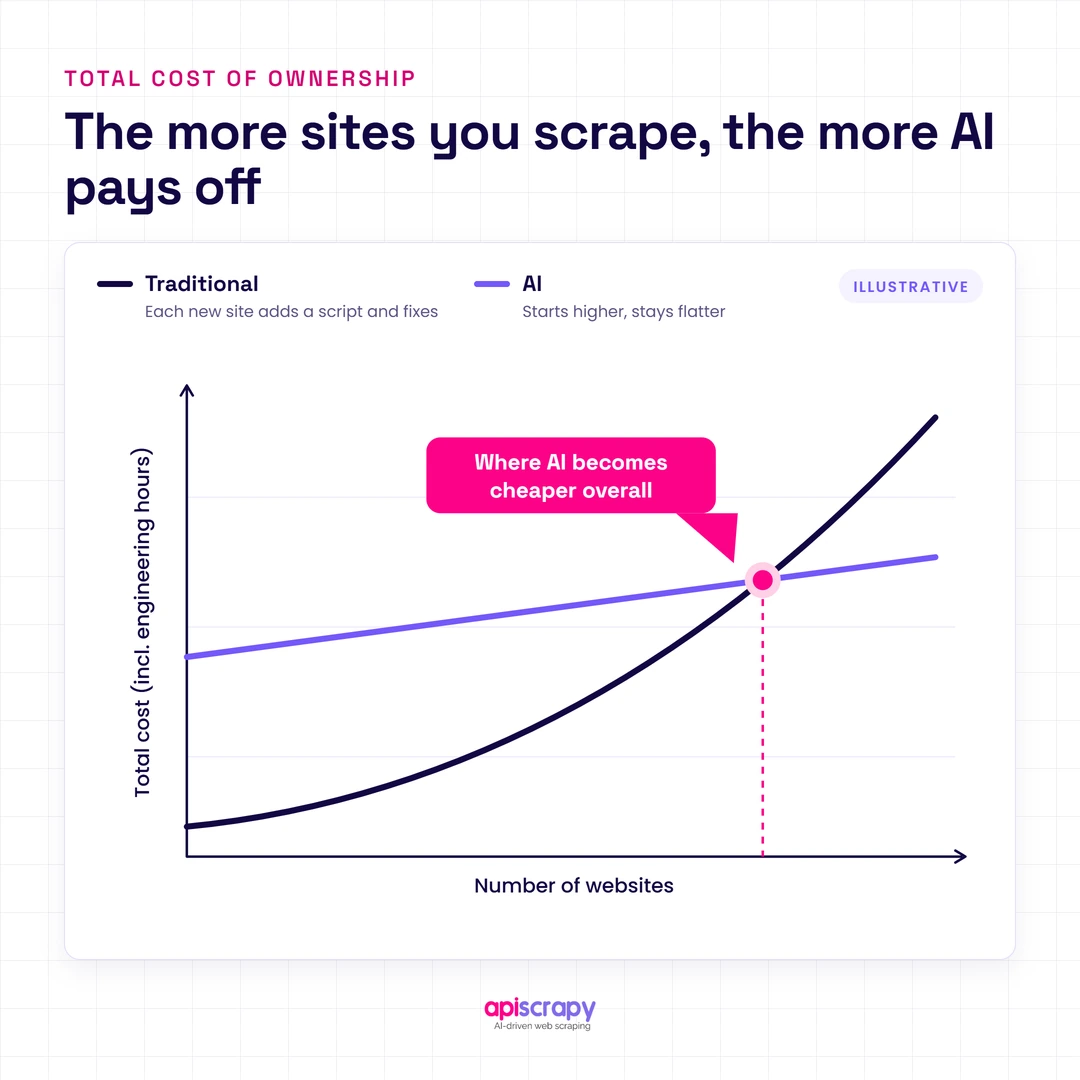
Traditional scraping costs less to start, but expenses climb fast once you add sites, since each new source needs its own script and its own fixes.
Maintenance and Technical Overhead
AI data extraction shifts maintenance from your engineering team to the service provider, freeing developers to focus on product work instead of scraper repairs.
What Are the Benefits of Using AI Data Extraction?
- Adapts automatically to layout and structural changes, cutting the manual rewrites traditional scraping demands
- Extracts data from JavaScript-heavy and dynamically loaded pages that static scrapers often render incorrectly
- Reduces the engineering hours needed to maintain hundreds of site-specific scripts across a growing pipeline
- Handles anti-bot measures and access restrictions more gracefully than static request-based scraping
- Delivers structured, cleaned data faster, since pattern recognition reduces the manual quality-check step
- Scales across new websites without requiring a developer to write a fresh script for each source
What to Look for in an AI Data Extraction Service
Accuracy and Data Quality Guarantees
Ask any AI data extraction service what accuracy rate they guarantee and how they validate output, since small errors compound quickly across large datasets.
Handling of Dynamic, JavaScript-Heavy Sites
Confirm the service renders JavaScript-heavy pages correctly, since many retail and travel sites load pricing data only after the initial page load.
Scalability and Pricing Model
Check whether pricing scales sensibly with data volume and website count, and whether new sources can be added without a lengthy onboarding process each time.
Compliance and Ethical Practices
Confirm the service respects robots.txt, rate limits, and the data privacy regulations relevant to your industry and target regions.
Support and Customization
Evaluate how responsive support is when extraction breaks, and whether the service offers custom fields, delivery formats, and integration options your team needs.
Is AI Data Extraction the Right Choice for Your Business?
AI data extraction suits businesses tracking many websites with frequently changing layouts, such as e-commerce price monitoring, market research, or lead generation at scale.
Traditional extraction still works well for teams with a handful of stable, well-structured sources and an in-house developer available to maintain scripts.
The deciding factors are usually data volume, how often source sites change, and whether your team has spare engineering capacity for ongoing upkeep.
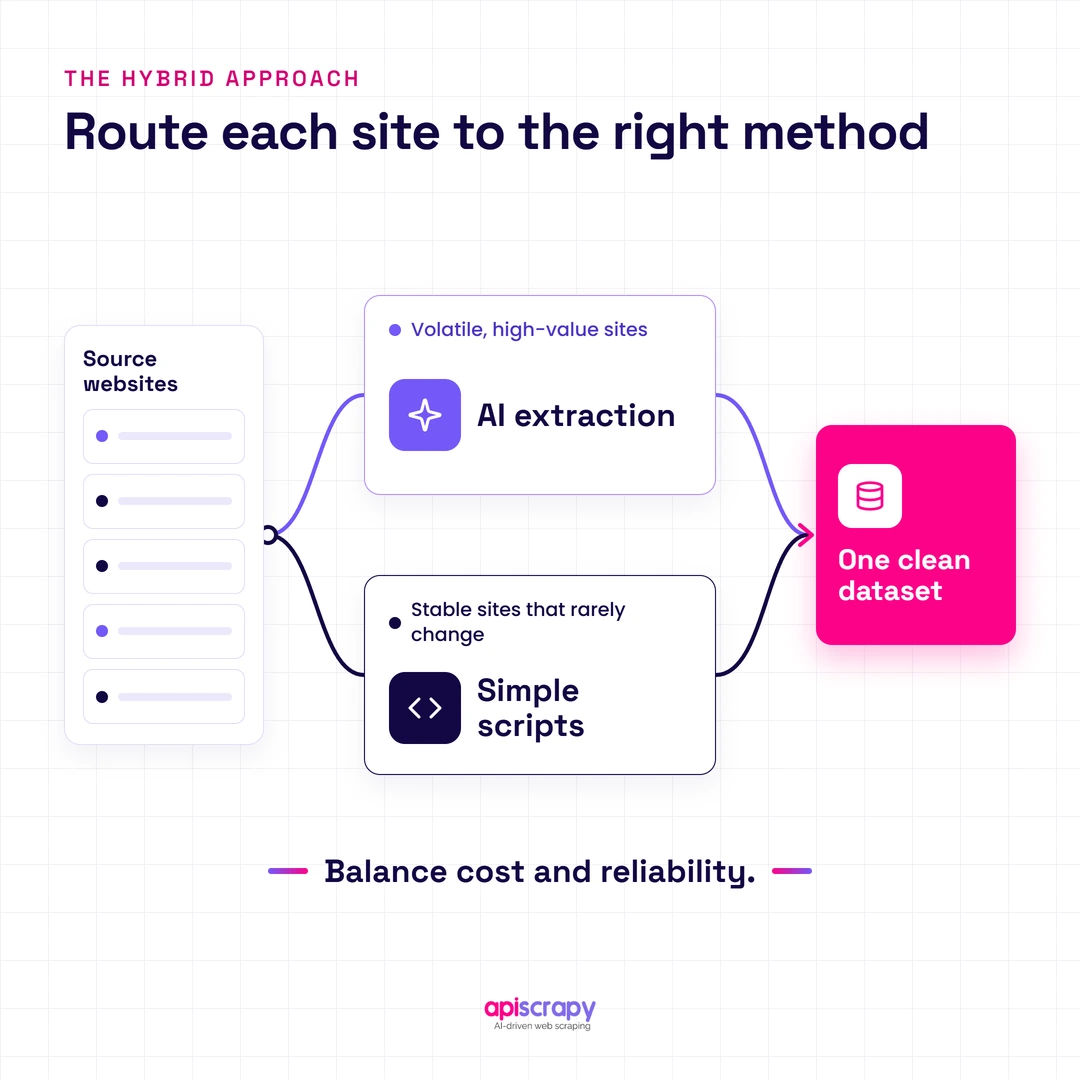
Many teams run a hybrid setup: AI extraction for volatile, high-value sources, and simple scripts for the few sites that rarely change.
APISCRAPY offers a managed AI data extraction service built for exactly this kind of scale. Book a demo with APISCRAPY to see how it handles your specific data sources before you commit.
Start Building Your Web Crawler Today
Conclusion
Neither approach is universally better. AI data extraction wins on adaptability and reduced maintenance, while traditional extraction wins on upfront simplicity for stable, small-scale needs.
Match the approach to your website count, layout stability, and available engineering time, and revisit that choice as your data needs grow. Book a demo with APISCRAPY to see how a managed AI data extraction service handles that shift for you.
Frequently Asked Questions
Can AI data extraction completely replace traditional web scraping?
Not entirely. Simple, stable, single-source jobs often run just as well on a lightweight script without the added cost of a managed service. For frequently changing, large-scale, or JavaScript-heavy sites, though, AI data extraction reduces the maintenance and errors that traditional scraping struggles to manage.
Is AI data extraction more accurate than traditional scraping?
Generally yes, especially on dynamic pages, since it recognizes data patterns rather than depending on exact HTML positions that can shift overnight. Traditional scraping can match that accuracy on stable, simple pages, but its accuracy tends to drop the moment a site redesigns its layout.
Which is more cost-effective at scale: AI extraction or traditional scraping?
Traditional scraping looks cheaper upfront, but costs rise quickly once you factor in developer hours spent fixing scripts that break repeatedly. AI data extraction carries higher usage-based pricing but often costs less overall at scale, since it needs far less manual upkeep.
Can AI data extraction handle dynamic websites and changing page layouts better than traditional scraping?
Yes, this is one of AI extraction's clearest advantages, since it identifies data by context and pattern rather than a fixed selector path. Traditional scraping usually breaks the moment a site changes structure, requiring a developer to rewrite the extraction logic before data flows again.
Is a hybrid approach combining AI extraction and traditional scraping better than using either one alone?
For many teams, yes. It lets you apply AI extraction where sites change often and simple scripts where sources stay stable and predictable. This mix balances cost and reliability, reserving the higher-maintenance service for the sources that genuinely need adaptive extraction.