How to Scrape Redfin Property Data with Python (Step-by-Step Guide for 2026)
Redfin holds some of the richest U.S. housing data online, including live prices, listing status, price history, and neighborhood stats. Analysts and investors want it in structured form.
This guide shows you how to scrape Redfin with working code and helps you choose the right method.
The three methods we cover:
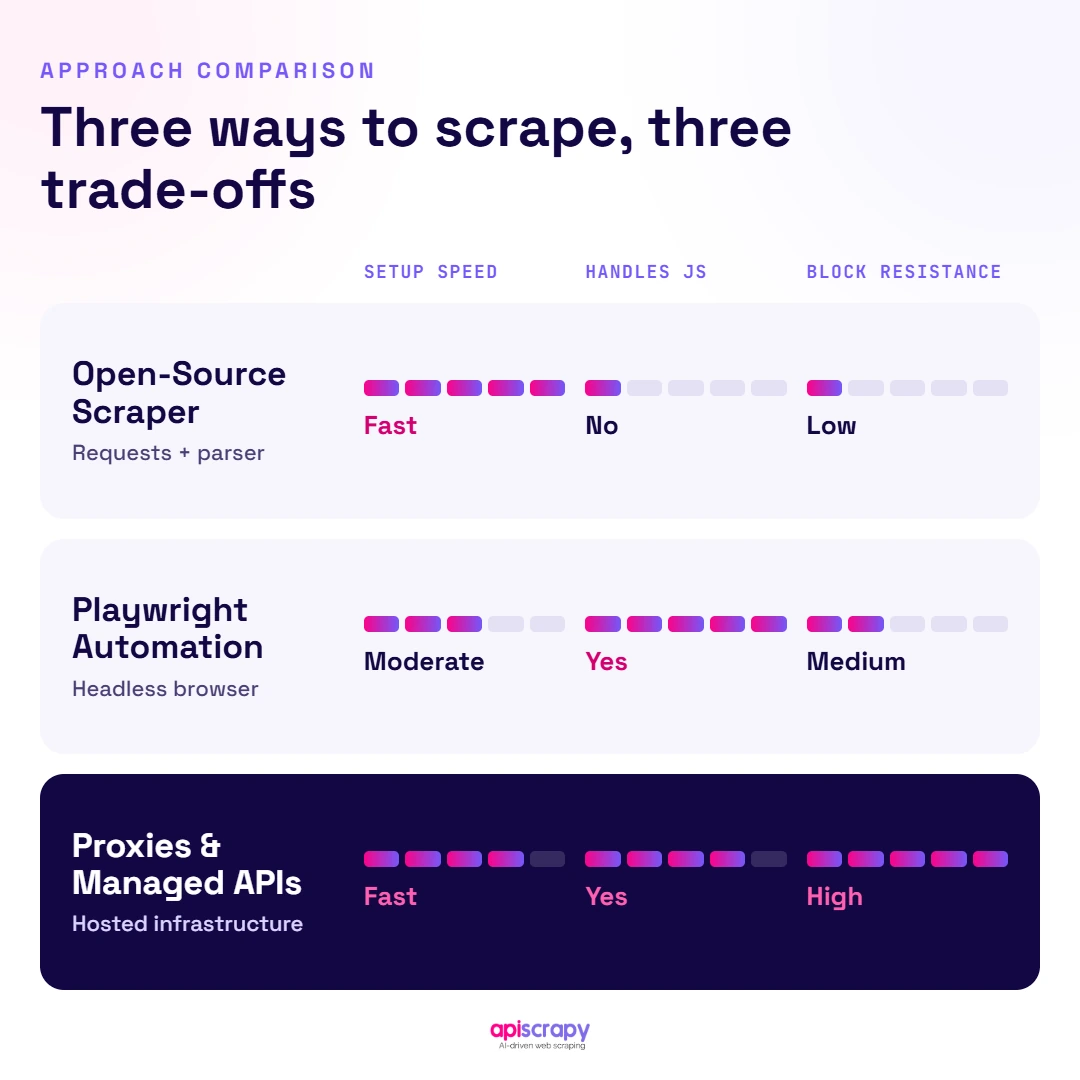
- Open-source redfin-scraper: the easiest starting point for small, one-off pulls.
- Playwright browser automation: best for custom scraping and JavaScript-heavy pages.
- Proxies and managed APIs: best for scale, with block handling and clean output.
We tested each method against live Redfin pages, watching for block rates, missing fields, and how often selectors broke.
Disclosure: APISCRAPY is our own service and appears in this guide. We’ve kept the comparison neutral.
Need Redfin data without the blocks and maintenance? Book a demo with APISCRAPY and get structured property data delivered on schedule.
- redfin-scraper is the fastest start for small pulls, but it relies on an unofficial internal API that can break.
- Playwright is best for JavaScript-heavy pages and search results that load dynamically.
- Managed APIs and proxies win at scale by handling CAPTCHAs, rate limits, and IP blocks.
- JSON-LD blocks change less often than page layouts, so they keep scrapers working longer.
- A 403 from requests.get() means Redfin spotted non-browser traffic. Switch to Playwright or a managed API.
- For free market-level data, Redfin’s Data Center offers downloadable datasets with no scraping needed.
Why Scrape Redfin.com?
Redfin exposes listing prices, sale status, days on market, price history, tax records, agent details, and neighborhood-level trends. This data has real commercial value.
Common use cases include:
- Investment analysis: spot undervalued properties and rental yield opportunities early.
- Market trend tracking: monitor price drops, inventory swings, and days on market by ZIP code.
- Lead generation: build prospect lists of active listings and recent sales.
- Valuation models: feed clean comparable-sales data into pricing algorithms.
The challenge is that Redfin renders much of its content dynamically and uses anti-bot protection. A basic script often works for a few requests, then gets blocked.
How to Scrape Redfin Property Pages with APISCRAPY
A Redfin property page contains the address, price, beds, baths, square footage, lot size, year built, listing status, and price history. These are the fields most teams extract.
Method 1: The Code Approach (Python and BeautifulSoup)
This suits developers who want full control and are working with a small number of URLs.
Steps:
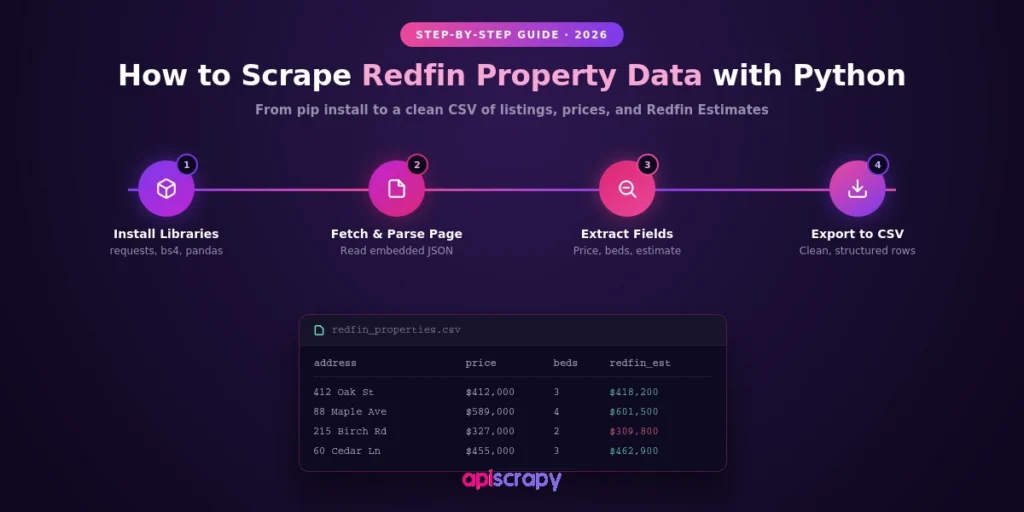
- Install the libraries:
pip install requests beautifulsoup4. - Send a request with realistic browser headers.
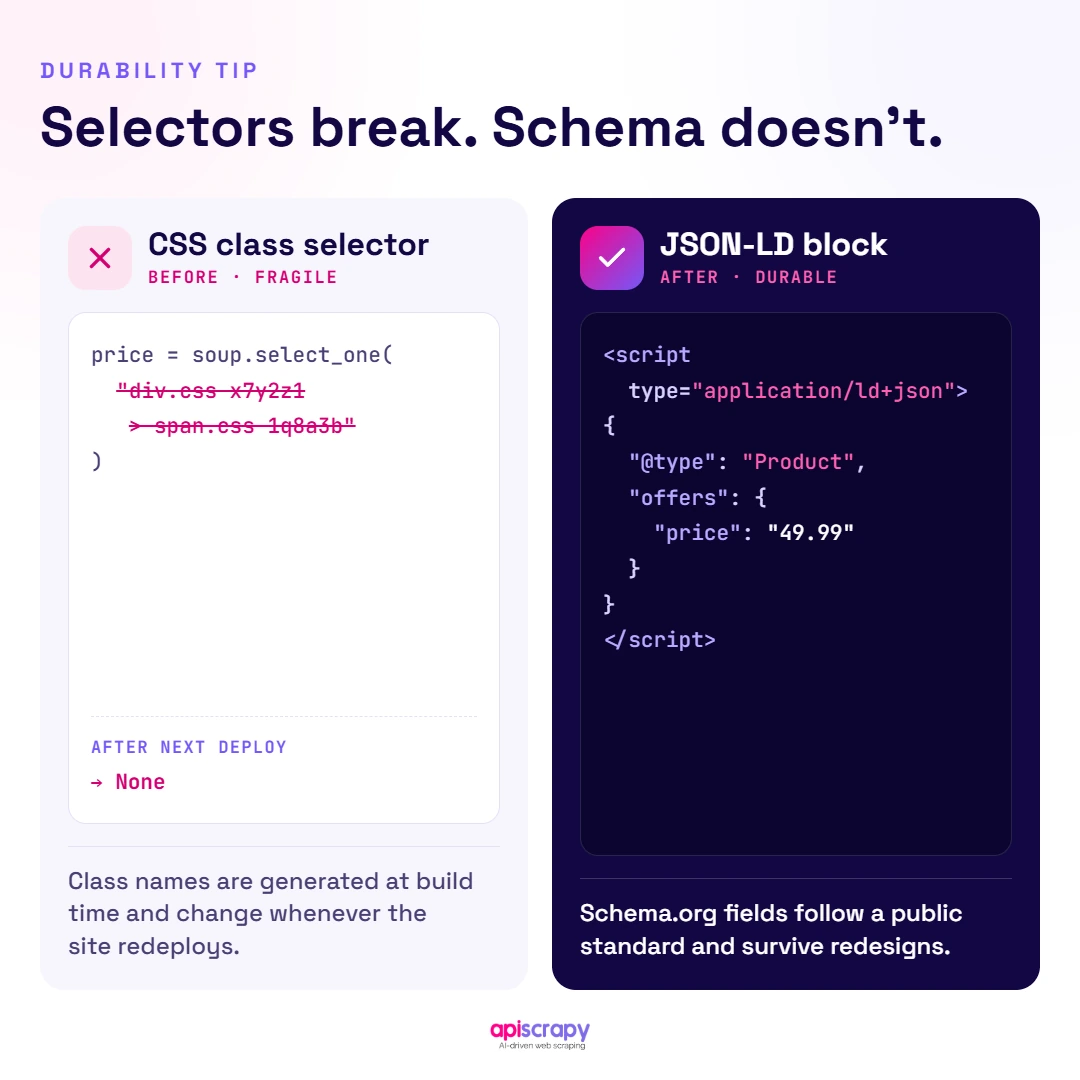
- Parse the embedded JSON-LD block instead of fragile CSS classes.
- Save the fields to CSV or JSON.
import requests, json

from bs4 import BeautifulSoup

url = "https://www.redfin.com/CA/San-Francisco/example-home/home/12345"

headers = {

"User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 "

"(KHTML, like Gecko) Chrome/124.0 Safari/537.36",

"Accept-Language": "en-US,en;q=0.9",

}

resp = requests.get(url, headers=headers, timeout=30)

resp.raise_for_status()

soup = BeautifulSoup(resp.text, "html.parser")

for tag in soup.find_all("script", type="application/ld+json"):

data = json.loads(tag.string)

print(data)
A practical tip from testing: structured data blocks change far less often than page layout, so they make your scraper more durable.
The limitation is that plain requests often return a 403 error or incomplete content on JavaScript-rendered sections. When that happens, move to browser automation or a managed API.
Method 2: No-Code Visual Scrapers
This suits non-developers and teams that need a quick export without writing code.
Steps:
- Paste the Redfin property URL into the scraping service.
- Select the fields you want, such as price, address, and beds.
- Run the extraction.
- Export to CSV, Excel, or JSON.
The trade-off is flexibility. No-code services are fast to start but can struggle with custom logic or very large volumes.
How to Scrape Redfin.com Search Results
Search result pages are where bulk collection begins. They give you the property links that you then feed into a property page scraper.
Method 1: No-Code and Pre-Built Scrapers (Fastest)
A pre-built Redfin scraper accepts a search URL or a city and returns listings without any coding.
Why teams choose it:
- Speed: you can have results within minutes.
- Pagination handled: the service crawls every results page for you.
- Structured output: fields arrive clean and ready for analysis.
This is the best fit for one-time research or teams without engineering capacity. The limit is customization at high volume.
Method 2: Custom Python Scraping
Custom scraping gives you control over filters, pagination, and output. For Redfin, a browser automation library like Playwright works better than plain requests because search pages load results dynamically.
Steps:
- Build the search URL with your city, ZIP, and filters.
- Load the page in a headless browser and wait for listings to render.
- Extract the property links from each results page.
- Paginate, then pass the links to your property page scraper.
from playwright.sync_api import sync_playwright

search_url = "https://www.redfin.com/city/17151/CA/San-Francisco"

with sync_playwright() as p:

browser = p.chromium.launch(headless=True)

page = browser.new_page()

page.goto(search_url, wait_until="networkidle")

page.wait_for_selector("a[href*='/home/']")

links = page.eval_on_selector_all(

"a[href*='/home/']",

"els => [...new Set(els.map(e => e.href))]"

)

print(len(links), "property links found")

browser.close()
Open-source options like the redfin-scraper library take a different route. They call Redfin’s unofficial internal API and are faster, but they can break whenever Redfin changes its endpoints.
At volume, expect CAPTCHAs, rate limits, and IP blocks. Rotating residential proxies, randomized delays, and retry logic become essential. This is where a managed extraction service saves the most time, because it handles proxies, browser fingerprints, and selector maintenance for you.
Is It Legal to Scrape Redfin?
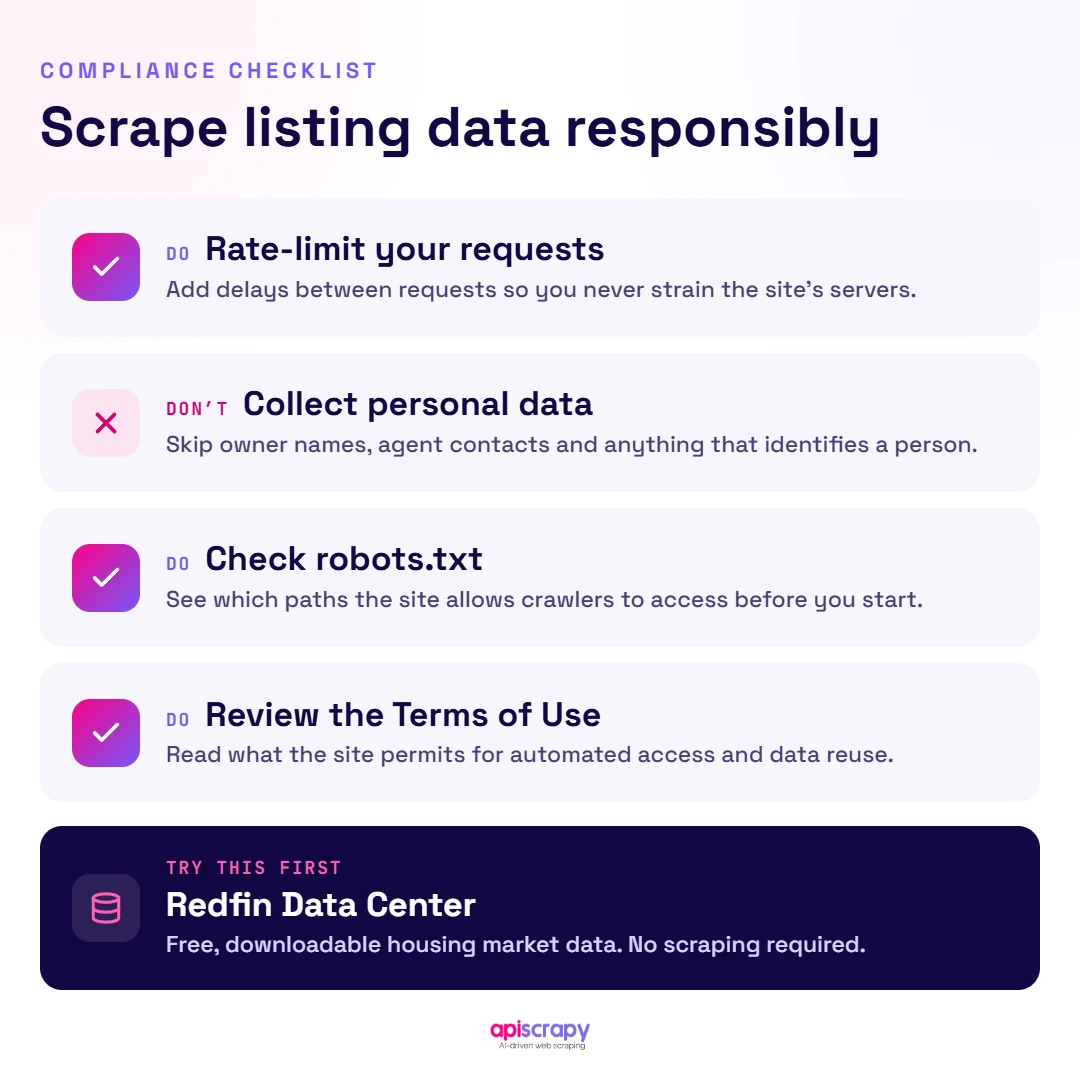
Scraping publicly visible data is not automatically illegal, but Redfin’s Terms of Use restrict automated access. Much of the listing content also originates from MLS feeds, which carry their own licensing rights. Legality depends on what you collect, how you use it, and where you operate.
Check Redfin’s robots.txt file, and remember that personal use and commercial use are treated differently.
Responsible scraping practices:
- Rate limit your requests so you never strain Redfin’s servers.
- Avoid personal data, such as private contact details.
- Review the Terms of Use before commercial deployment.
- Use official feeds where they fit. Redfin’s Data Center offers free downloadable market-level data, including median sale prices, inventory, and price drops.
This is general information, not legal advice. Consult qualified counsel before building a commercial data product.
Start Building Your Web Crawler Today
Conclusion
You now have three routes to Redfin data. Open-source scripts suit quick experiments, Playwright suits custom builds, and managed services suit scale.
Pick by volume and skill level. For a handful of listings, code it yourself. For recurring, large-scale collection, a managed service usually costs less than the engineering time spent fighting blocks.
APISCRAPY helps teams that need reliable, high-volume Redfin property data without maintaining scrapers, proxies, or CAPTCHA workarounds.
Need Redfin data without the blocks and maintenance? Book a demo with APISCRAPY and get structured property data delivered on schedule.
FAQs
Does Redfin have an official public API for developers?
No. Redfin has no public listing API. It offers the Data Center, which provides downloadable market-level datasets.
How do I bypass the CAPTCHA block when scraping Redfin?
Slow your request rate, rotate residential proxies, and use a real browser. A managed scraping service handles this automatically.
Why does requests.get() return a 403 Forbidden error on Redfin?
Redfin detects non-browser traffic. Add realistic headers, or use Playwright or a managed API for reliable access.
How do I scrape Redfin search results pages for bulk property links?
Load each results page in a headless browser, extract every /home/ link, and paginate. Then feed those links into your property scraper.
Can I use Selenium or Playwright to export Redfin listings to a CSV file?
Yes. Extract fields with either one, then save them using Python's csv module or pandas to_csv().