
Web Scrapers
45 articles
 Web Scrapers
A Web Scraper’s Guide to robots.txt: How to Crawl Websites Responsibly
robots.txt is an important crawler signal, not a technical access-control mechanism. It is part of the Robots Exclusion Protocol and communicates how…
 Web Scrapers
What Is a Managed Web Scraping Service?
Provider manages proxy rotation, browser rendering, and anti-bot handling (CAPTCHAs, IP blocks, fingerprinting) end to end Raw HTML gets cleaned and structured…
 Web Scrapers
Web Scraping Best Practices in 2027
Anti-bot systems are now the biggest scale barrier: IP reputation checks, TLS/browser fingerprinting, and behavioral scoring have made blocks harder to avoid…
 Web Scrapers
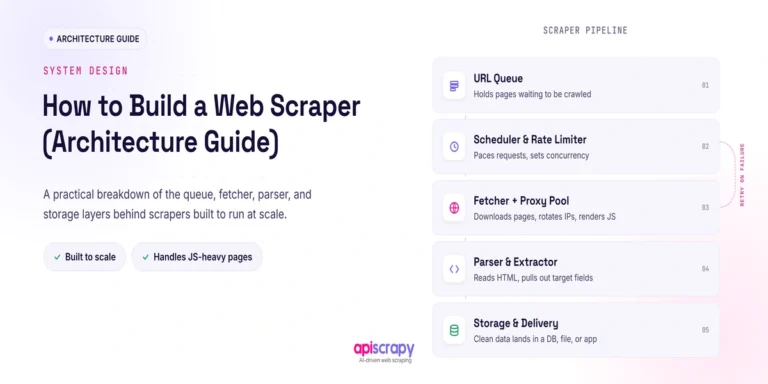
How to Build a Web Scraper (Architecture Guide)
Architecture beats scripting at scale: a single script works for a few hundred pages, but volume, anti-bot defenses, and multi-site targets demand…
 Web Scrapers
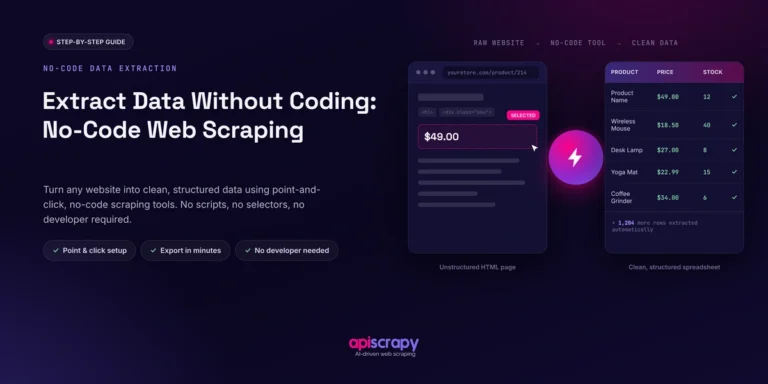
How to Extract Data Without Coding: No-Code Web Scraping
No-code scraping is now mainstream: as of 2026, extracting structured data no longer requires developers or Python as a plain-language instructions or…
 Web Scrapers
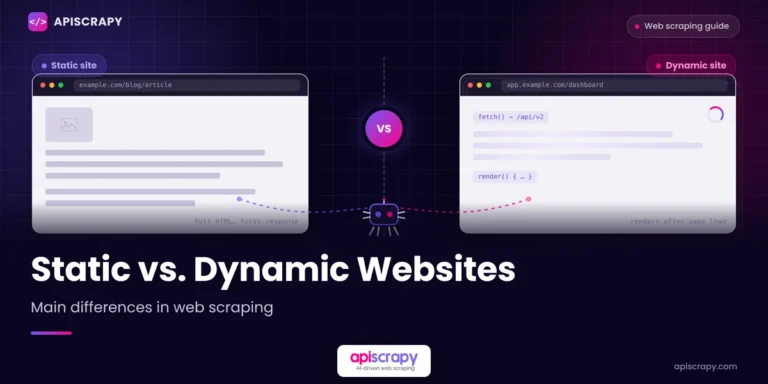
Static vs. Dynamic Websites: Main Differences in Web Scraping
The decision comes down to sanctioned access, not preference. If a data owner offers a clean API, that's usually the stable path.…